Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
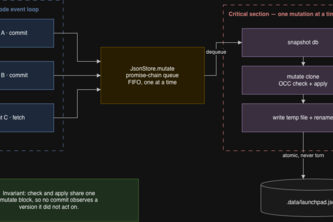
Middleware that keeps parallel coding agents out of each other's way, by versioning what every agent reads as well as what it writes.
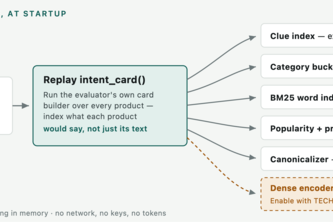
A shopper sort of knows what they want; it's buried somewhere in 50,000 products. Our agent gets ten turns to find it — no language model, no API calls. Yet, it gets it right every time!
AgentTrace adds Glass Box middleware to every agent run, capturing redacted traces, failure evidence, recovery signals, and exportable audits so teams can trust and debug agents.
A private, offline-first shopping agent that understands evolving needs, adapts when shoppers change their minds, and finds the right product faster.
An autonomous ML research agent for KuaiRand-Pure that proves its improvements. A paired-seed bootstrap gate rejected five hypotheses and accepted one — numpy only, zero GPU, zero LLM tokens.
Conversational search engine built with an AI embedding model with no external API calling
A small autonomous loop for KuaiRand-Pure within-user ranking. It reproduces the official FM, tries one change at a time on validation only, then retrains and writes the test scores.
It is an agent that does the research, not just the training. It forms a hypothesis, writes the code, scores it with the official metric, and keeps only what clears the bar.
glhf
Tired of slow and costly AI search while shopping? We built an offline search agent that uses fast BM25 ranking and smart budget filters to match customers with the right products in fewer turns.
Git caught code collisions. Humans caught design collisions through communication. AI agents have neither. Shepherd detects when individually correct agents build a collectively broken system.
The security boundary for autonomous AI agents, enforcing scoped, revocable access before protected data ever reaches the runtime, from single agents to multi-agent teams.
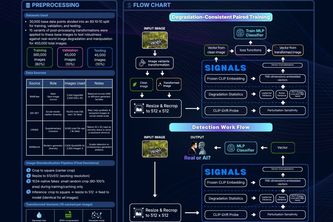
A frozen CLIP backbone plus a engineered signals. Trained with a paired clean/transformed loss that explicitly punishes the model for changing its answer when the image degrades.
TacoRank: an autonomous AI research team that plans, codes, breaks, recovers, and learns — beating a short-video ranking baseline while you sleep.
An offline, zero-token shopping agent that finds the hidden product in a 50,000 item catalog in under two turns on average.
An LLM-powered shopping copilot that uncovers the right product from 50,000 options in 10 turns or fewer using intelligent questions and hybrid search.
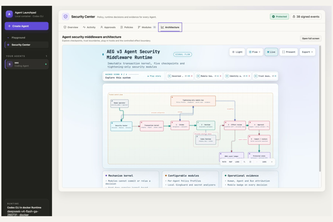
A lightweight, pluggable middleware that stages, inspects, approves, and safely commits every AI agent side effect.
Embedflix: An autonomous ML research agent that iterates on a video recommender system: researching techniques, writing code, training models, and improving ranking quality without human intervention.
An autonomous recommender research agent that safely proposes, tests, and audits model improvements inside an isolated sandbox.
An agent that talks to a shopper the way a good in-store assistant would, understand what they say, ask sharp questions, and narrows a catalog down to the right product in a handful of turns.
Autonomous ML Research Agent for Recommender Systems
Kafka-powered Agent supervision with real-time tracing, threat detection, automatic recovery, and an evidence-grounded operator chatbot.
A conversational shopping agent that knows when to ask and when to answer, locating your exact product in ~4 turns with zero hosted-LLM cost.
InverseCart turns 50,000 products into intent hypotheses and decides whether to recommend now or ask one more question—reaching 0.9832 on the public benchmark with zero runtime model calls.
217 – 240 of 614